
Before the next word: a visual lab for temperature and top-p
Reshape a token distribution, then inspect how a sample is chosen.
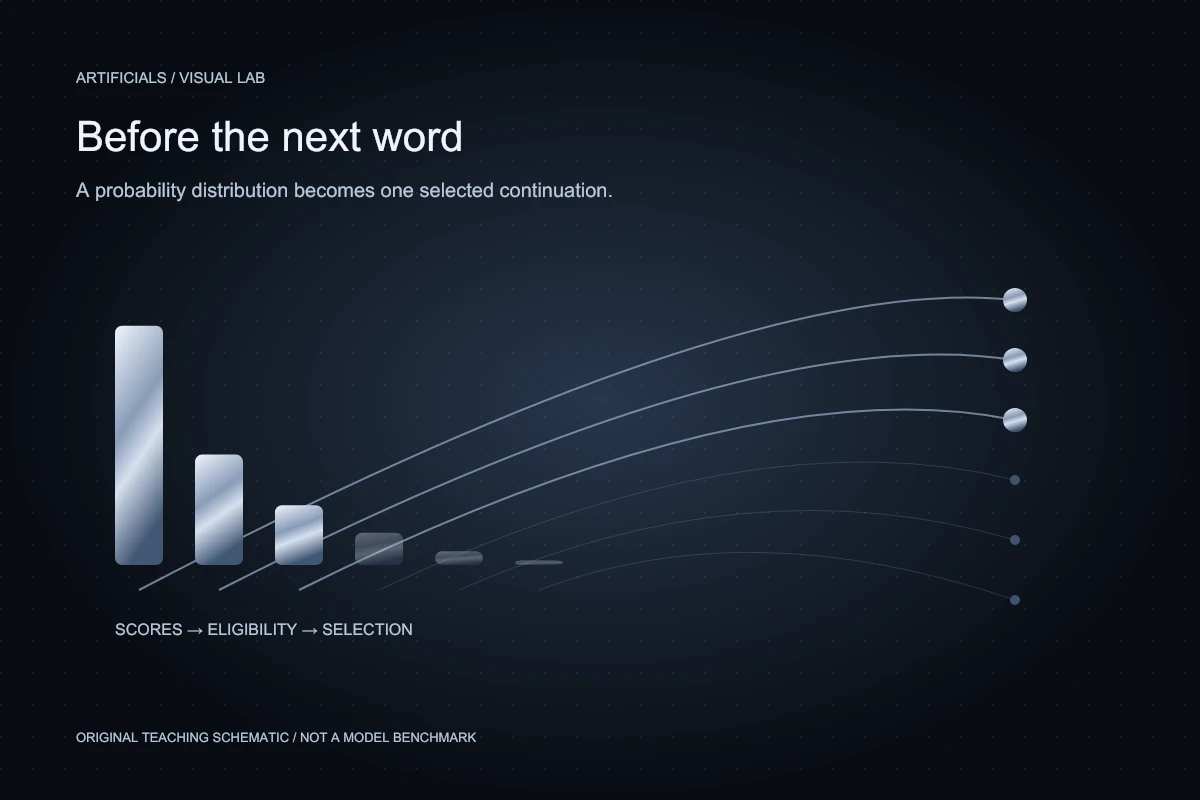
Two answers can start from the same question and diverge before the first sentence is complete. That does not necessarily mean the model retrieved different facts or changed its knowledge. A generation system also has to choose a continuation from its possible next tokens. The rule used for that choice can change the answer even when the underlying model parameters stay fixed.
This laboratory isolates that decision. You can reshape an invented distribution, remove its lower-probability tail, and move a selection marker through the remaining choices. There is no language model running behind these controls. The six token labels and their scores are authored examples, chosen so that the arithmetic remains visible. They are not captured outputs from any commercial model.
The goal is to develop a practical distinction between what a model scores, what a decoder permits, and what a particular generation selects. Keeping those three ideas separate helps explain variation without describing every setting as a creativity slider or treating a repeated answer as evidence of truth.
Reshape the distribution before choosing a token
One score list, two probability stages
Change concentration, then eligibility. Filled bars show the final distribution; fine lines show probabilities before filtering. Each row includes both values.
- doorlogit 3.050.4%Before filter 48.3% · Eligible · after filter 50.4%
- windowlogit 2.427.6%Before filter 26.5% · Eligible · after filter 27.6%
- studiologit 1.815.2%Before filter 14.5% · Eligible · after filter 15.2%
- booklogit 1.06.8%Before filter 6.5% · Eligible · after filter 6.8%
- pathlogit 0.20.0%Before filter 2.9% · Excluded · after filter 0.0%
- signallogit -0.70.0%Before filter 1.2% · Excluded · after filter 0.0%
The first figure starts with six invented logits: 3.0, 2.4, 1.8, 1.0, 0.2, and minus 0.7. A logit is a score before normalization, not a probability. The example labels are readable words, but actual token vocabularies also contain fragments, spaces, punctuation, and special symbols. A real model's candidate set is much larger than this deliberately small display.
Move temperature while leaving top-p at one. The bars show two stages: the probability after temperature scaling and the final probability after the top-p filter. When no tail is removed, those values agree. Lowering temperature concentrates probability toward the largest score. Raising it spreads more probability toward alternatives. Neither operation changes which underlying logit is largest in this example.
The calculation divides every logit by a positive temperature, subtracts the largest scaled value for numerical stability, exponentiates, and normalizes the results. Subtracting a common constant does not change the resulting probabilities. It prevents unnecessary numerical overflow without changing the mathematical question. The laboratory keeps temperature above zero and treats greedy selection as a separate decision rule.
A probability is conditional, not a truth score
The score for a next token belongs to a particular prefix. If the prefix changes, the model generally produces a different distribution. This is why a single probability chart cannot describe an entire answer. After each selected token is appended, the next selection is conditioned on a longer sequence.
Suppose the visible continuation begins with “The workshop opened a”. A model may give high probability to a familiar phrase that fits the surrounding style. That preference does not establish that the workshop actually opened anything. Fluent continuation and factual support are different properties, and changing a sampling parameter does not add missing evidence to the prompt.
For the same reason, do not present a selected token's probability as the confidence that the whole response is correct. An answer can contain many individually ordinary tokens and still assert an unsupported event. Product-level confidence requires a defined task, an evaluation method, and often evidence outside the generation distribution.
Top-p changes the eligible set
Now lower top-p. The laboratory sorts tokens by their temperature-adjusted probabilities and keeps the smallest leading group whose cumulative mass reaches the chosen threshold. The token that crosses the boundary remains eligible. Probabilities for retained tokens are then divided by their retained total, so the final distribution sums to one again.
The number of retained tokens is not fixed. If one candidate already holds most of the probability, a relatively high threshold may keep only that candidate. If probability is spread evenly, the same threshold may retain several. This is different from top-k, which limits the number of candidates rather than specifying a cumulative probability target.
Nucleus sampling was introduced by Holtzman and colleagues to address problems they observed in open-ended text generation. Its historical motivation is useful context, but it does not imply that one threshold is best for every contemporary application. The paper studies a decoding approach, not a universal setting for correctness, safety, or useful prose.
Read the original research paper on arXiv
Read the two bars together
A common misreading happens when someone sees a token's final probability increase after filtering and concludes that the model became more certain. In this experiment the original logits did not change. Removing alternatives and renormalizing increased the retained candidates' shares of a smaller distribution. That is a decoder operation, not new supporting evidence.
Try a threshold that leaves one token. Its final probability becomes one hundred percent even if its pre-filter probability was much lower. The display makes that difference explicit. A user interface that shows only the final number can conceal how much probability mass was discarded before the selection was made.
The order of operations also matters. This laboratory applies temperature first and top-p second. Changing that sequence can change which candidates cross a threshold. When reproducing a model experiment, record the actual implementation and processing order rather than assuming that similarly named controls behave identically across every library and endpoint.
Move the draw through the probability intervals
A draw selects an interval
Fixed temperature 1.0 and top-p 0.9. The sweep represents possible uniform draws; it is not a random sequence or a new generation.
Reduced motion is on. Use the slider to explore at your own pace.
u = 0.000 lies inside this token's interval.
- 1. door[0.000, 0.504)50.4%
- 2. window[0.504, 0.780)27.6%
- 3. studio[0.780, 0.932)15.2%
- 4. book[0.932, 1.000)6.8%
Square bracket includes the lower bound; round bracket excludes the upper bound. Displayed boundaries are rounded; selection uses full precision.
The second figure holds a distribution fixed and places its probabilities along a ruler from zero to one. Each token owns an interval whose width matches its probability. A uniform draw selects the interval containing it. Wider intervals are selected more frequently over many independent draws, but a narrow eligible interval can still be selected on a particular attempt.
Here the marker follows scrolling, moves backward when you scroll upward, and can be controlled manually. That sweep is a teaching animation, not a random-number generator. Its position stands in for a possible draw so that you can inspect the boundary. The intervals use temperature one and top-p 0.9, independently of the first figure's controls.
Notice that the final marker stops just below one. The usual conceptual sampling interval includes zero and excludes one. At a shared boundary, the choice belongs to the interval that starts there. The visible percentages are rounded for reading; the selection code uses the unrounded numbers. Small display-rounding differences should not be mistaken for an extra token.
Greedy does not mean globally best
Greedy decoding chooses the highest-scored eligible next token at each step. It can be useful when variation is undesirable, but it is a local rule. It does not search every possible finished response and certify the most useful one. Even the most probable full sequence would not automatically be the most truthful or helpful answer for a reader.
Hugging Face's generation documentation distinguishes greedy decoding, sampling, and beam-based strategies. Its configuration reference also separates temperature and candidate filtering from length limits and stopping rules. Those distinctions are more useful than treating every generation control as interchangeable. Consult the exact model and library configuration before assuming that a parameter is available or active.
Hugging Face: Technical documentation
Hugging Face: Technical documentation
Design an experiment that can answer a question
Imagine an application that rewrites short help messages. Start with a fixed set of messages, a rubric for preserving instructions, and examples where wording changes could reverse the meaning. Compare settings across that set. Keep the prompt, model version, and output limit fixed while changing one decoding parameter at a time.
Measure more than whether the wording varies. Count missing steps, invented promises, broken formatting, and unnecessary length. Review whether variation helps the intended reader. A wider distribution may create useful alternative phrasings, but it may also make a previously rare error more visible. A narrower distribution can repeatedly produce the same mistake.
Use repeated generations when evaluating a stochastic setting. One attractive sample is an anecdote, not a description of the distribution. Report the number of attempts and inspect difficult examples separately. If a workflow retries until an acceptable response appears, include those rejected attempts in its cost and latency measurements rather than reporting only the winning output.
Reproducibility needs more than a seed
A seed can help reproduce a sampling sequence within a controlled implementation. It does not freeze every surrounding condition. Model revisions, numerical kernels, parallel execution, prompt formatting, and library changes can alter the calculation or the sequence of random operations. Treat reproducibility as an environment contract rather than a single integer copied into a settings panel.
For a regression test, save the inputs and the versioned generation configuration. Decide whether the requirement concerns exact text, valid structure, or preserved meaning. An exact-text comparison may be appropriate for a tightly controlled fixture; it can be too brittle for a user-facing paraphrase task. The acceptance rule should match the behavior the product actually promises.
Keep generation controls out of the role of security enforcement. An application should validate outputs and permissions independently of whether sampling is enabled. A deterministic unsafe action is still unsafe, and a low-temperature unsupported answer is still unsupported. The decoder influences selection; it is not the authorization system.
Take a distribution-shaped view of the answer
The most useful habit from this laboratory is to ask where a change entered the pipeline. Did the model's evidence change? Did its logits change? Did a decoder remove options? Or did a different draw select another eligible continuation? Each explanation points toward a different test and a different repair.
Use the first figure to separate concentration from filtering, and the second to separate eligibility from selection. Then evaluate the resulting complete answer against the task. You will have a clearer account of why outputs vary, without mistaking probability for truth or assuming that a single knob can optimize every kind of AI work.